Pangenome×Representation
To make population-scale analysis accessible, we represent pangenomes implicitly, without building a graph. Tracepoints compress alignments, and impg queries them to build graphs on demand.
We build and analyze pangenomes to study genome variation, cancer, and complex disease.
We work across the full pangenomics stack. With pangenome×representation we build implicit, queryable alignments and graphs, and with pangenome×association we use graph features as genetic markers. We apply them to pangenome×fragility in the human genome, to cancer×pangenomics in tumors, and to complex disease.
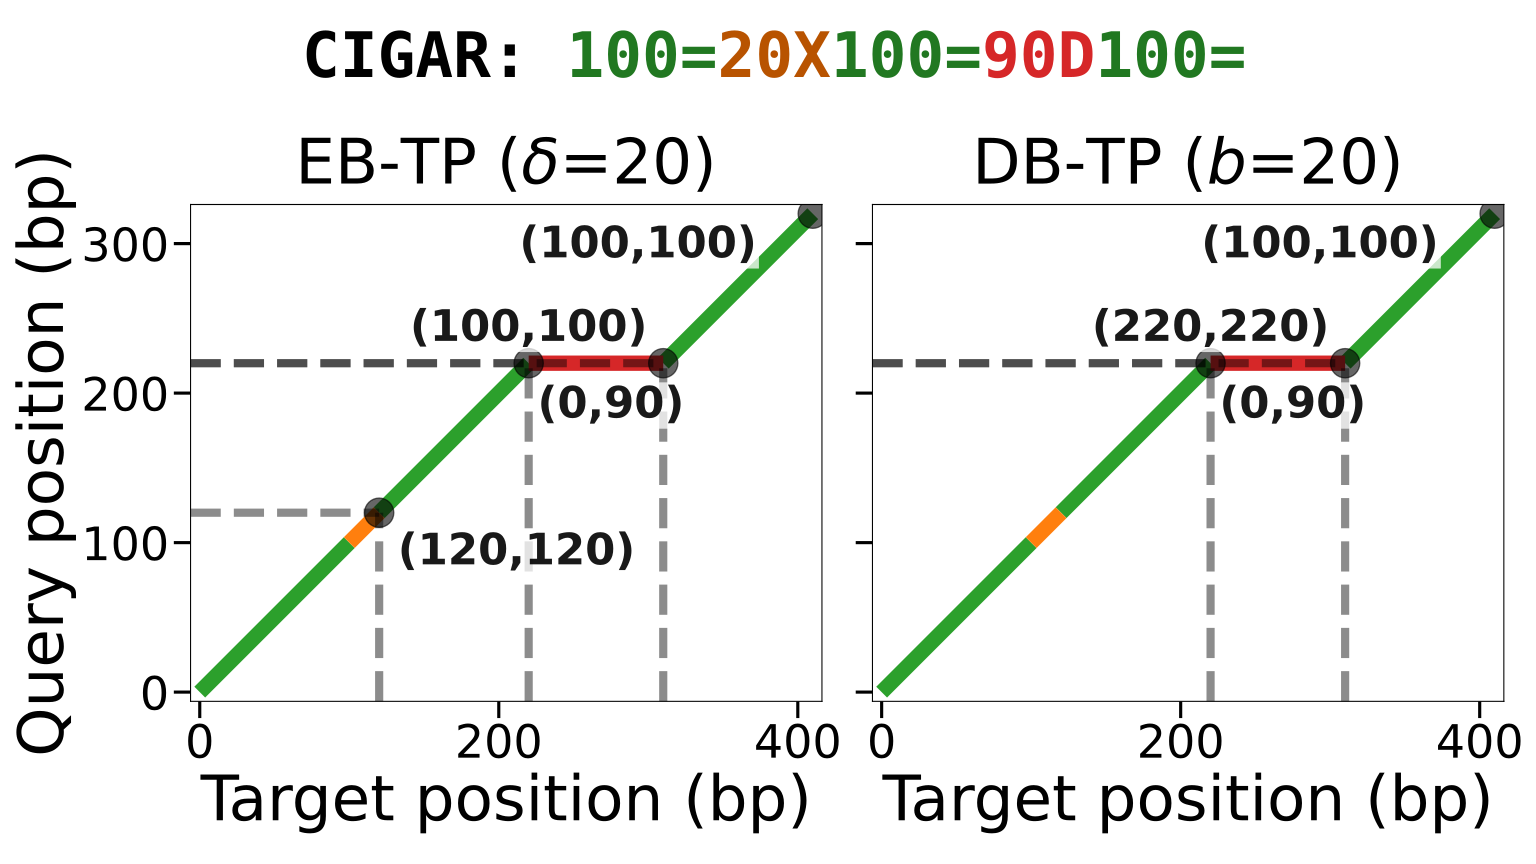
To make population-scale analysis accessible, we represent pangenomes implicitly, without building a graph. Tracepoints compress alignments, and impg queries them to build graphs on demand.
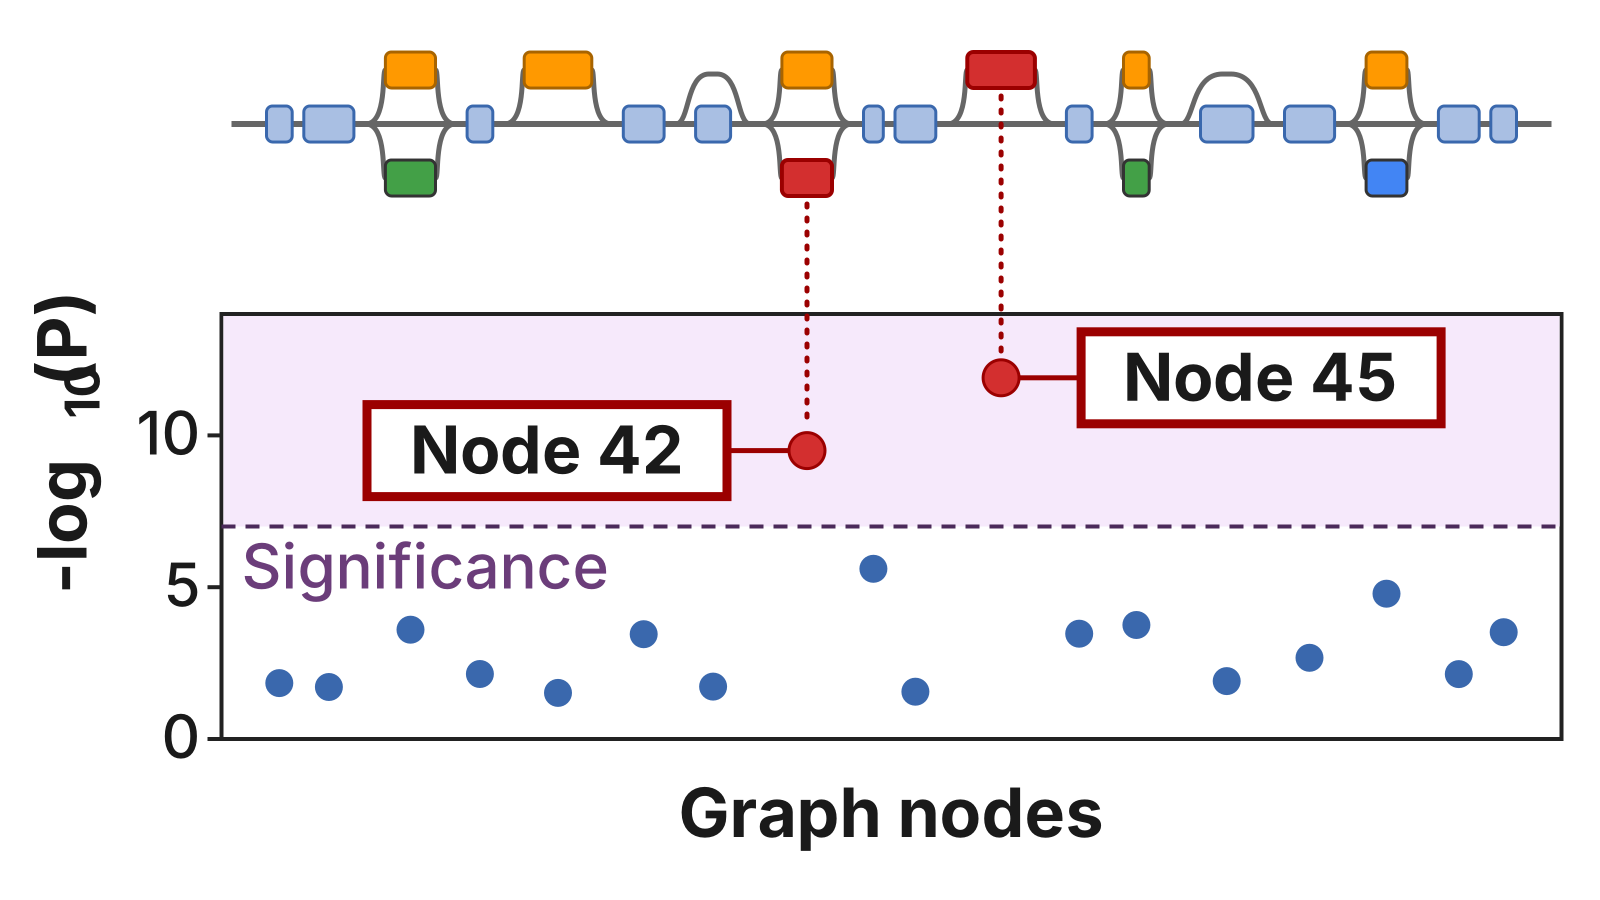
We find the variants behind traits and disease risk, using pangenome graph features, not variant calls, as markers. With long reads, we are resolving the hidden alleles on prostate cancer risk haplotypes.
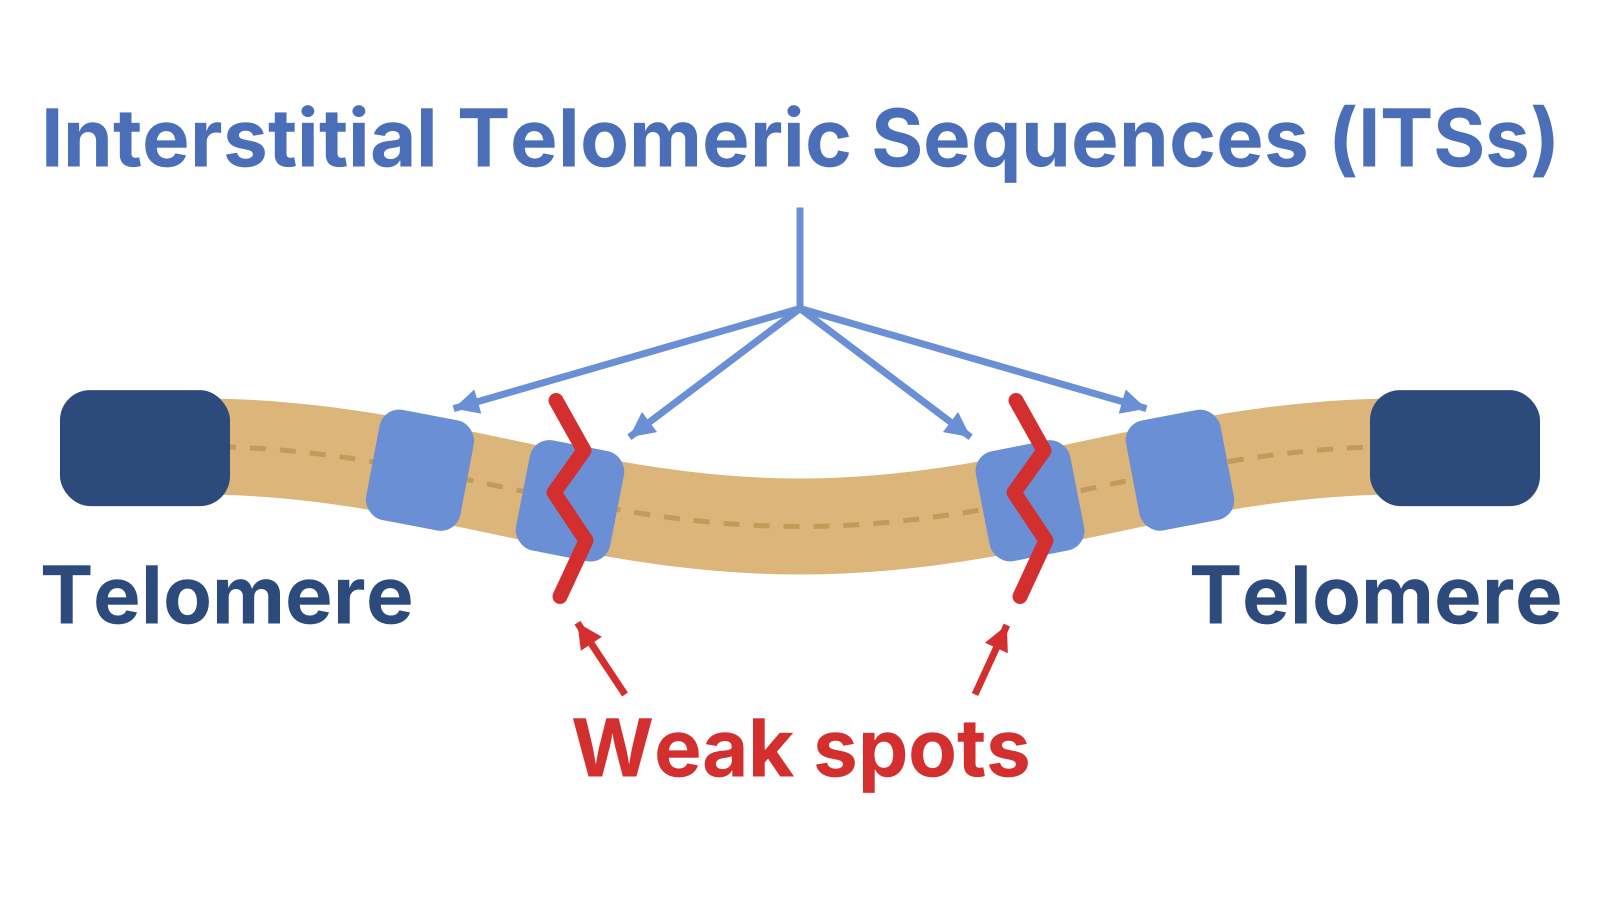
We study hidden telomere repeats in the human pangenome, weak spots where DNA can break. In glioblastoma, we read each DNA molecule on its own to find markers of unstable tumors and track their evolution.
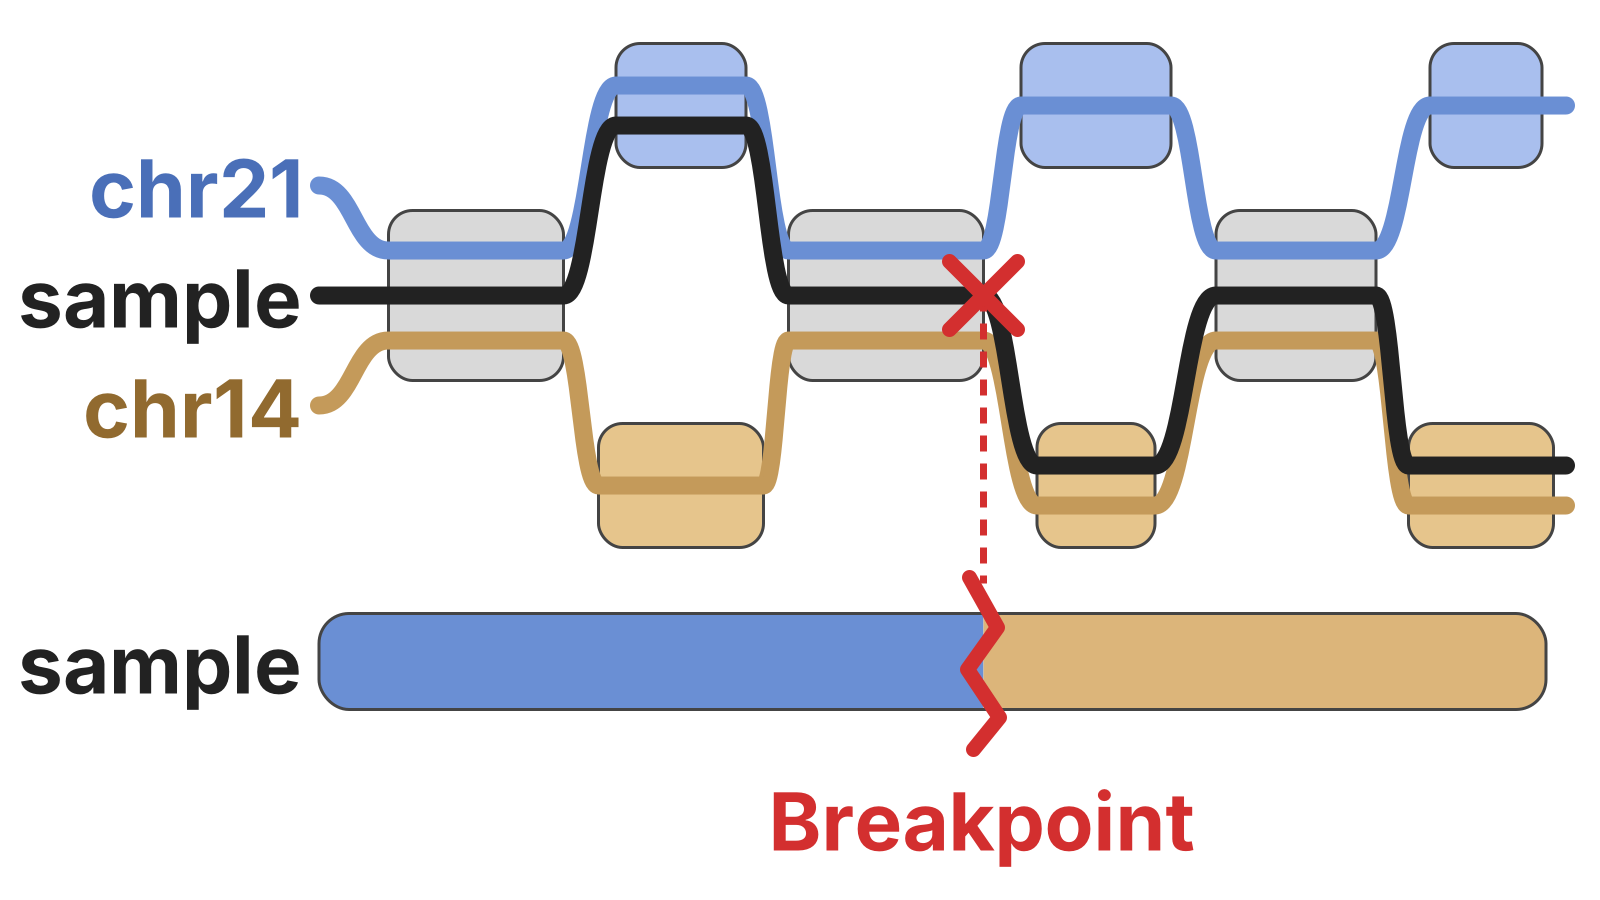
We find the somatic structural variants that a single reference misses. We build personalized pangenomes from tumor and matched normal samples with long-read sequencing and de novo assembly.
The lab opened in January 2026. We are actively building the team.
Full list on Google Scholar or ORCID.